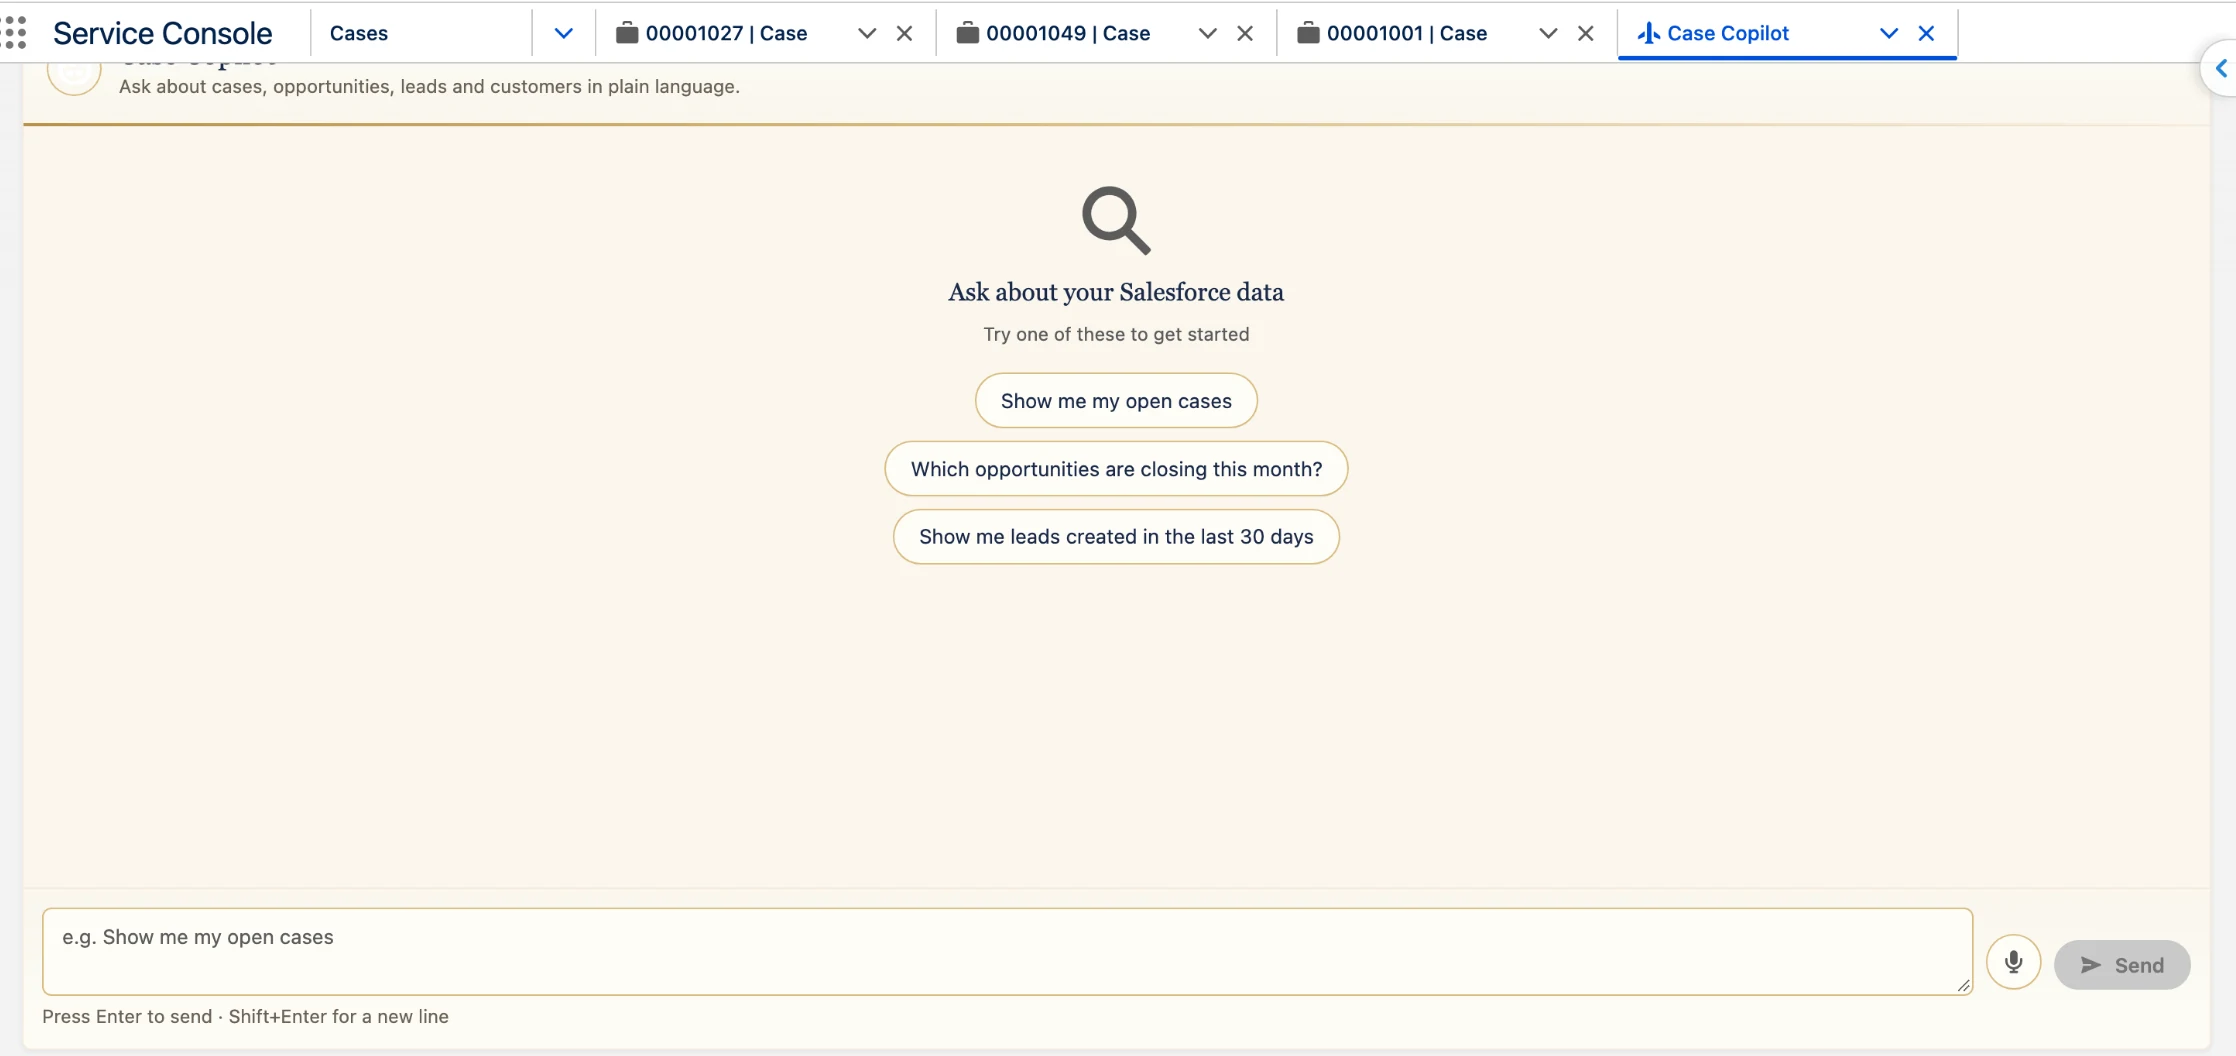
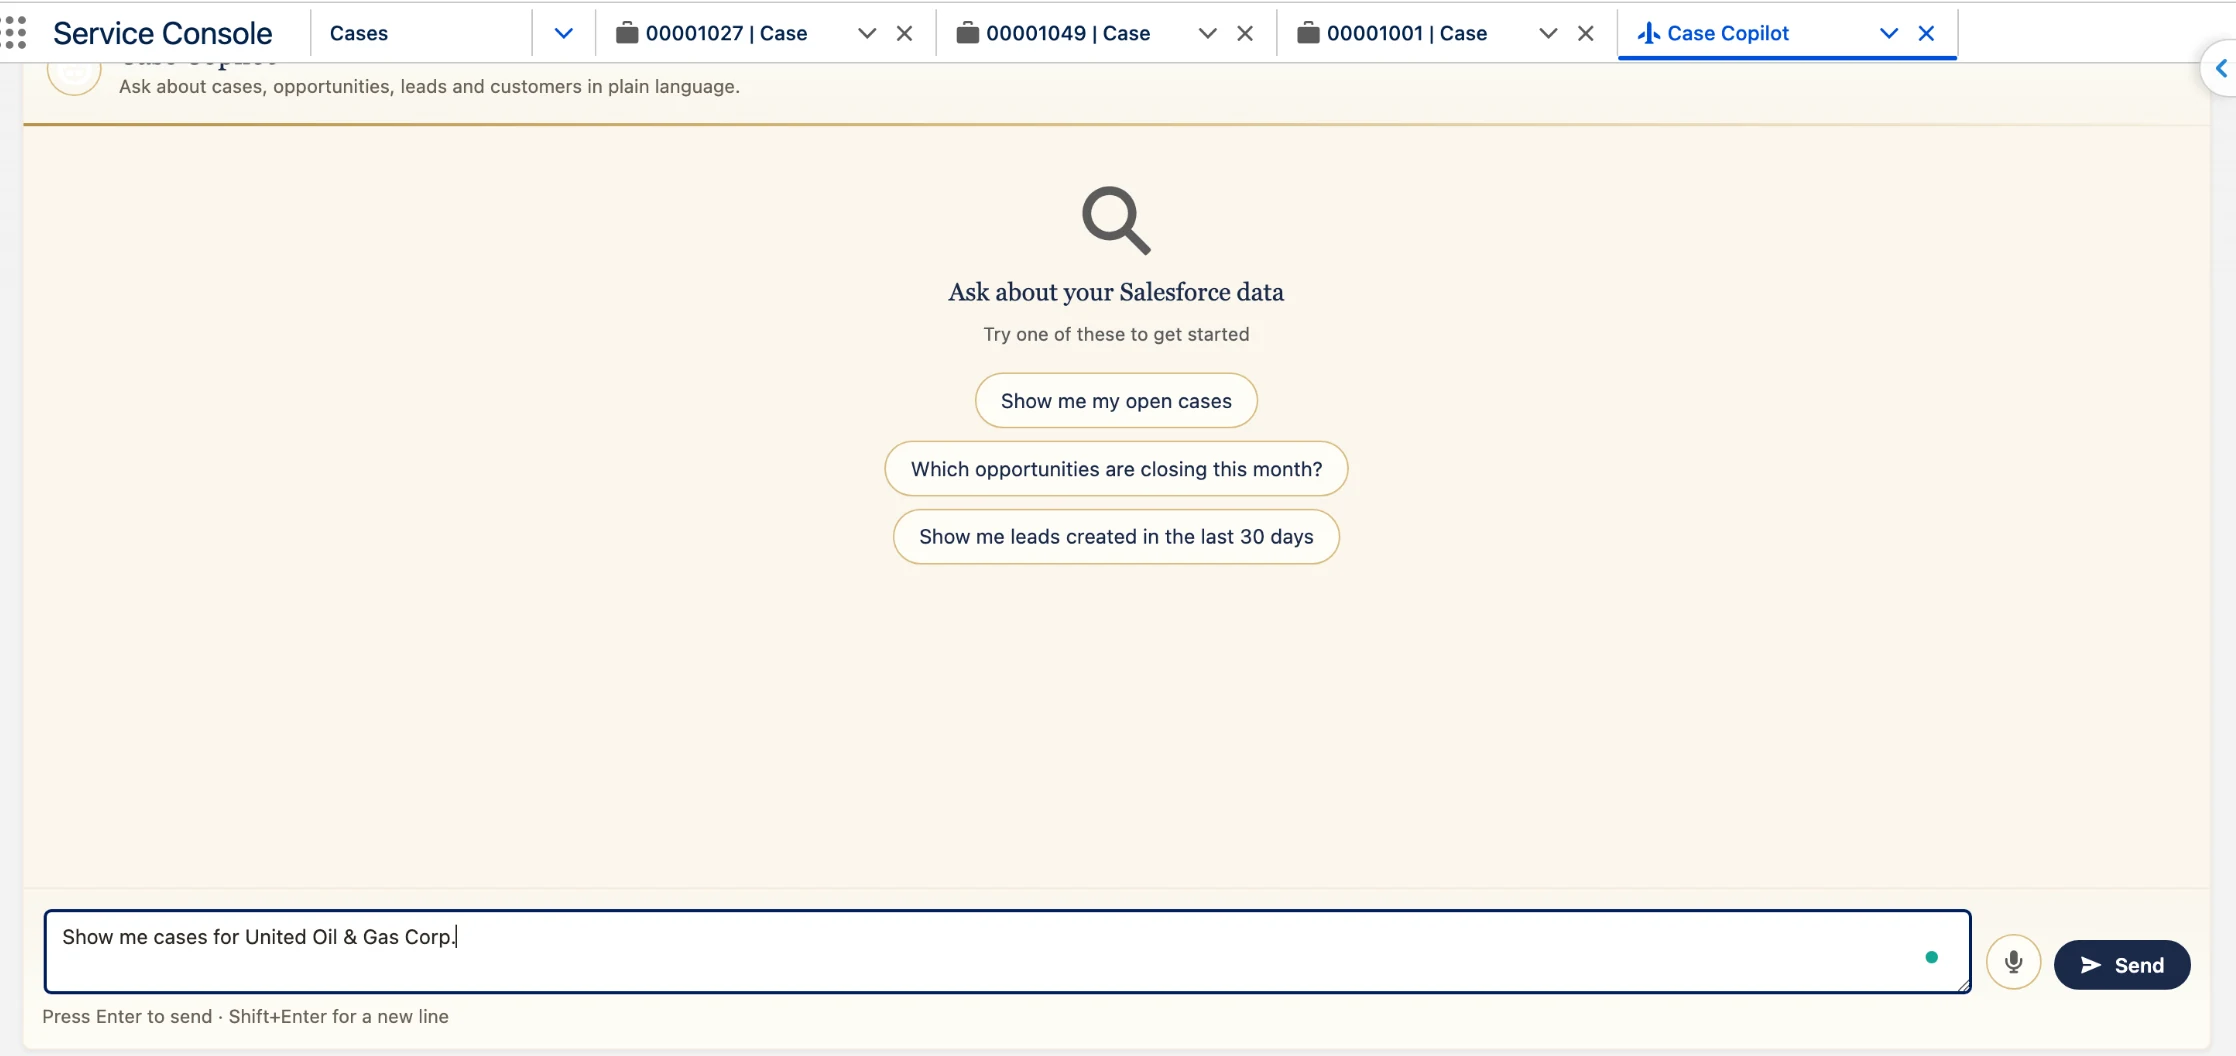
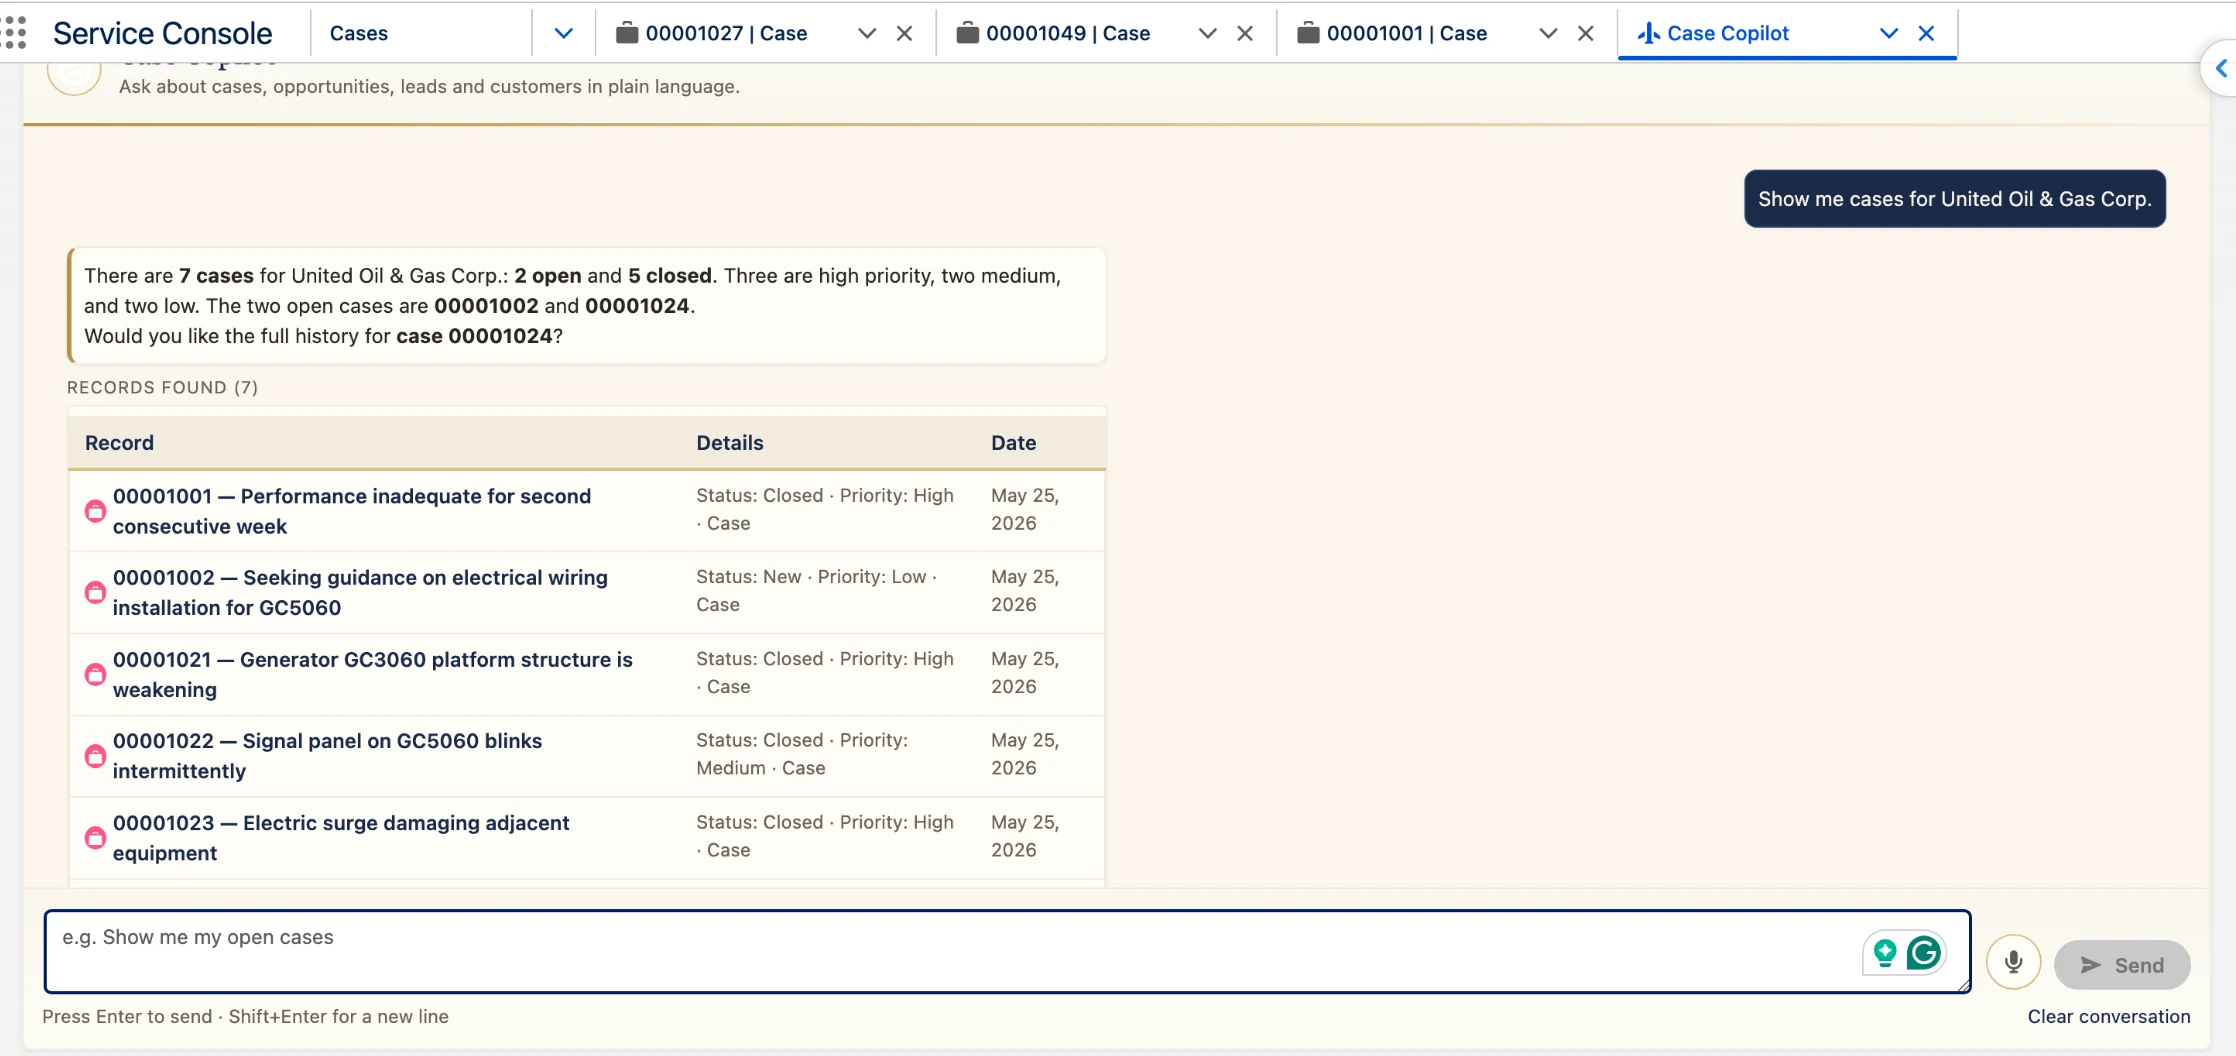
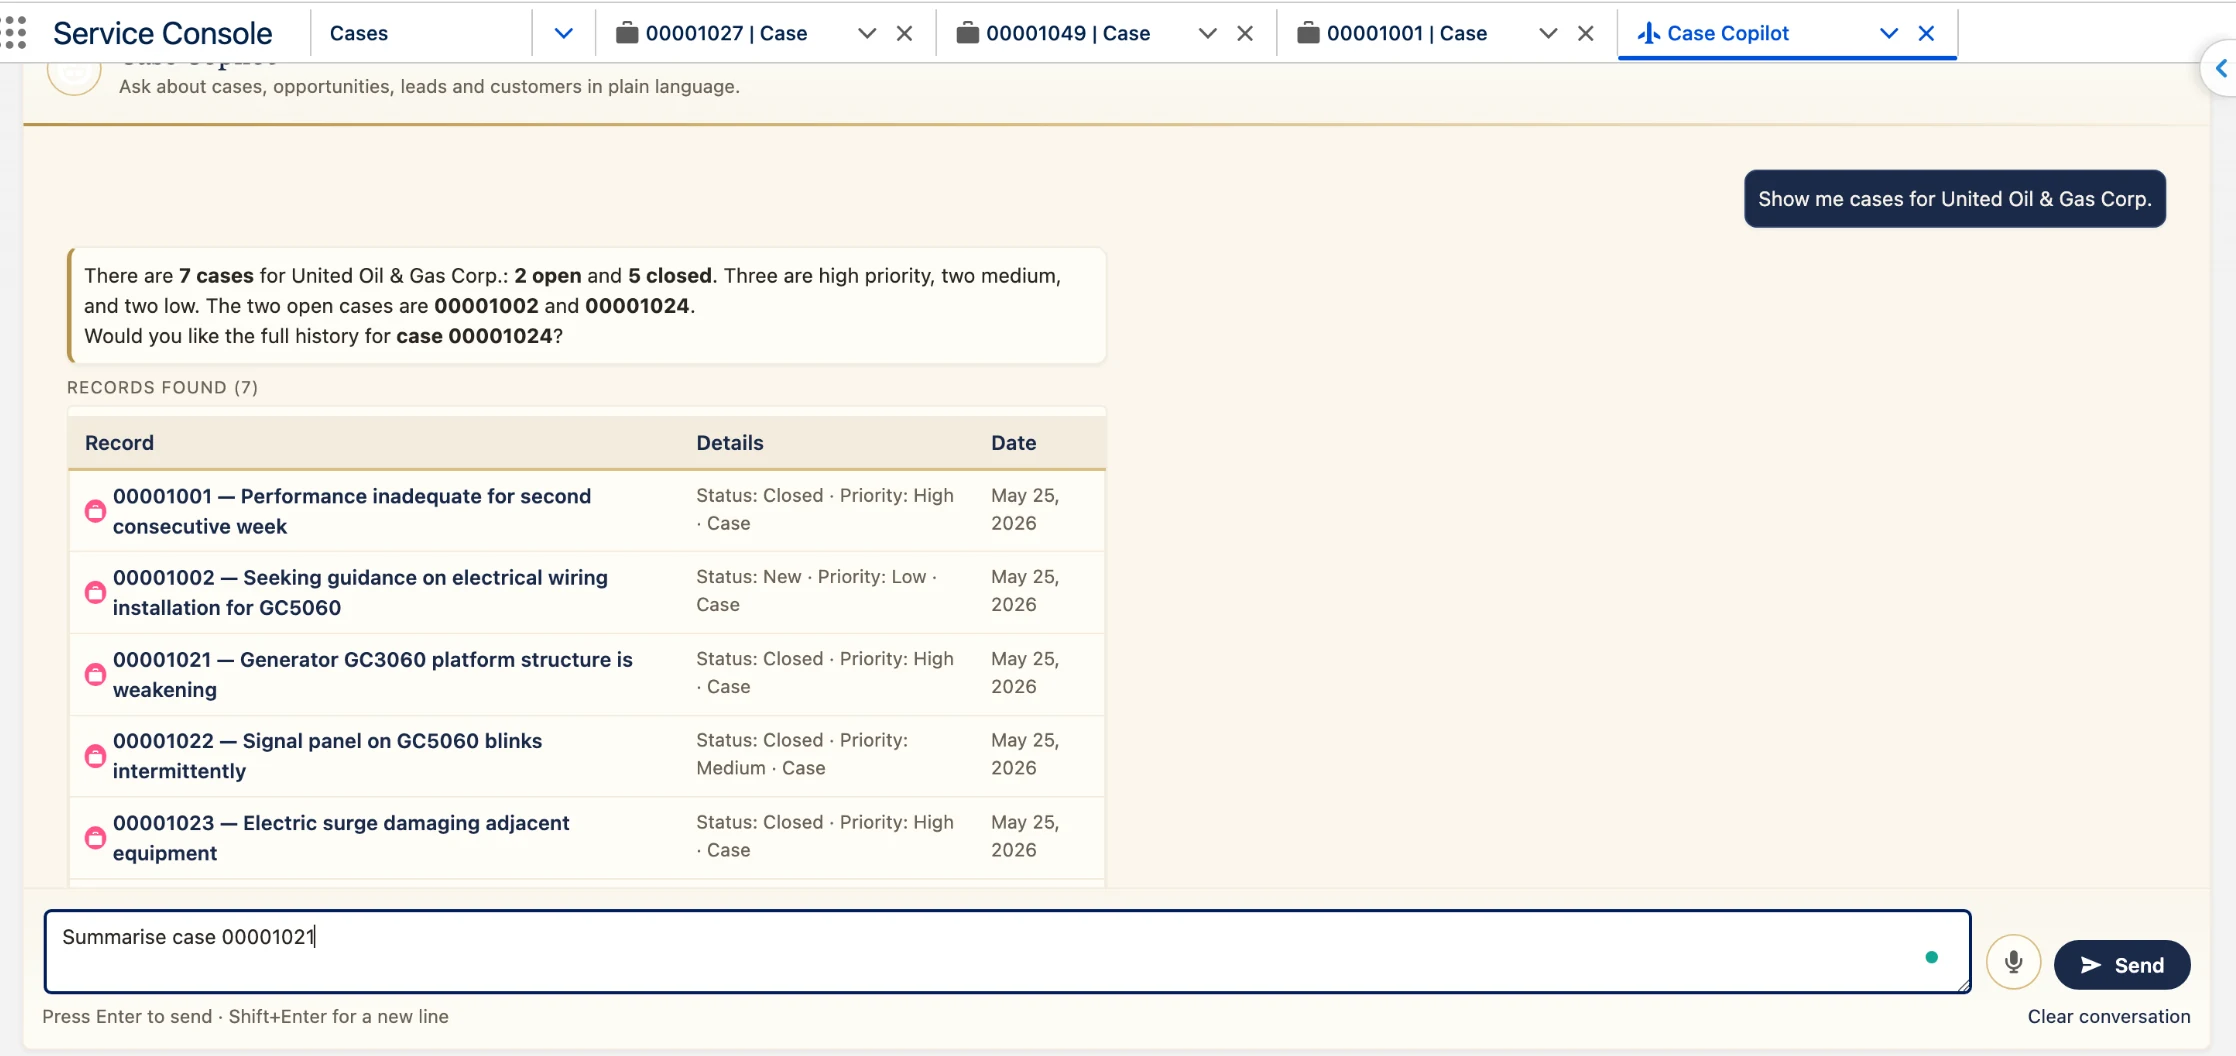
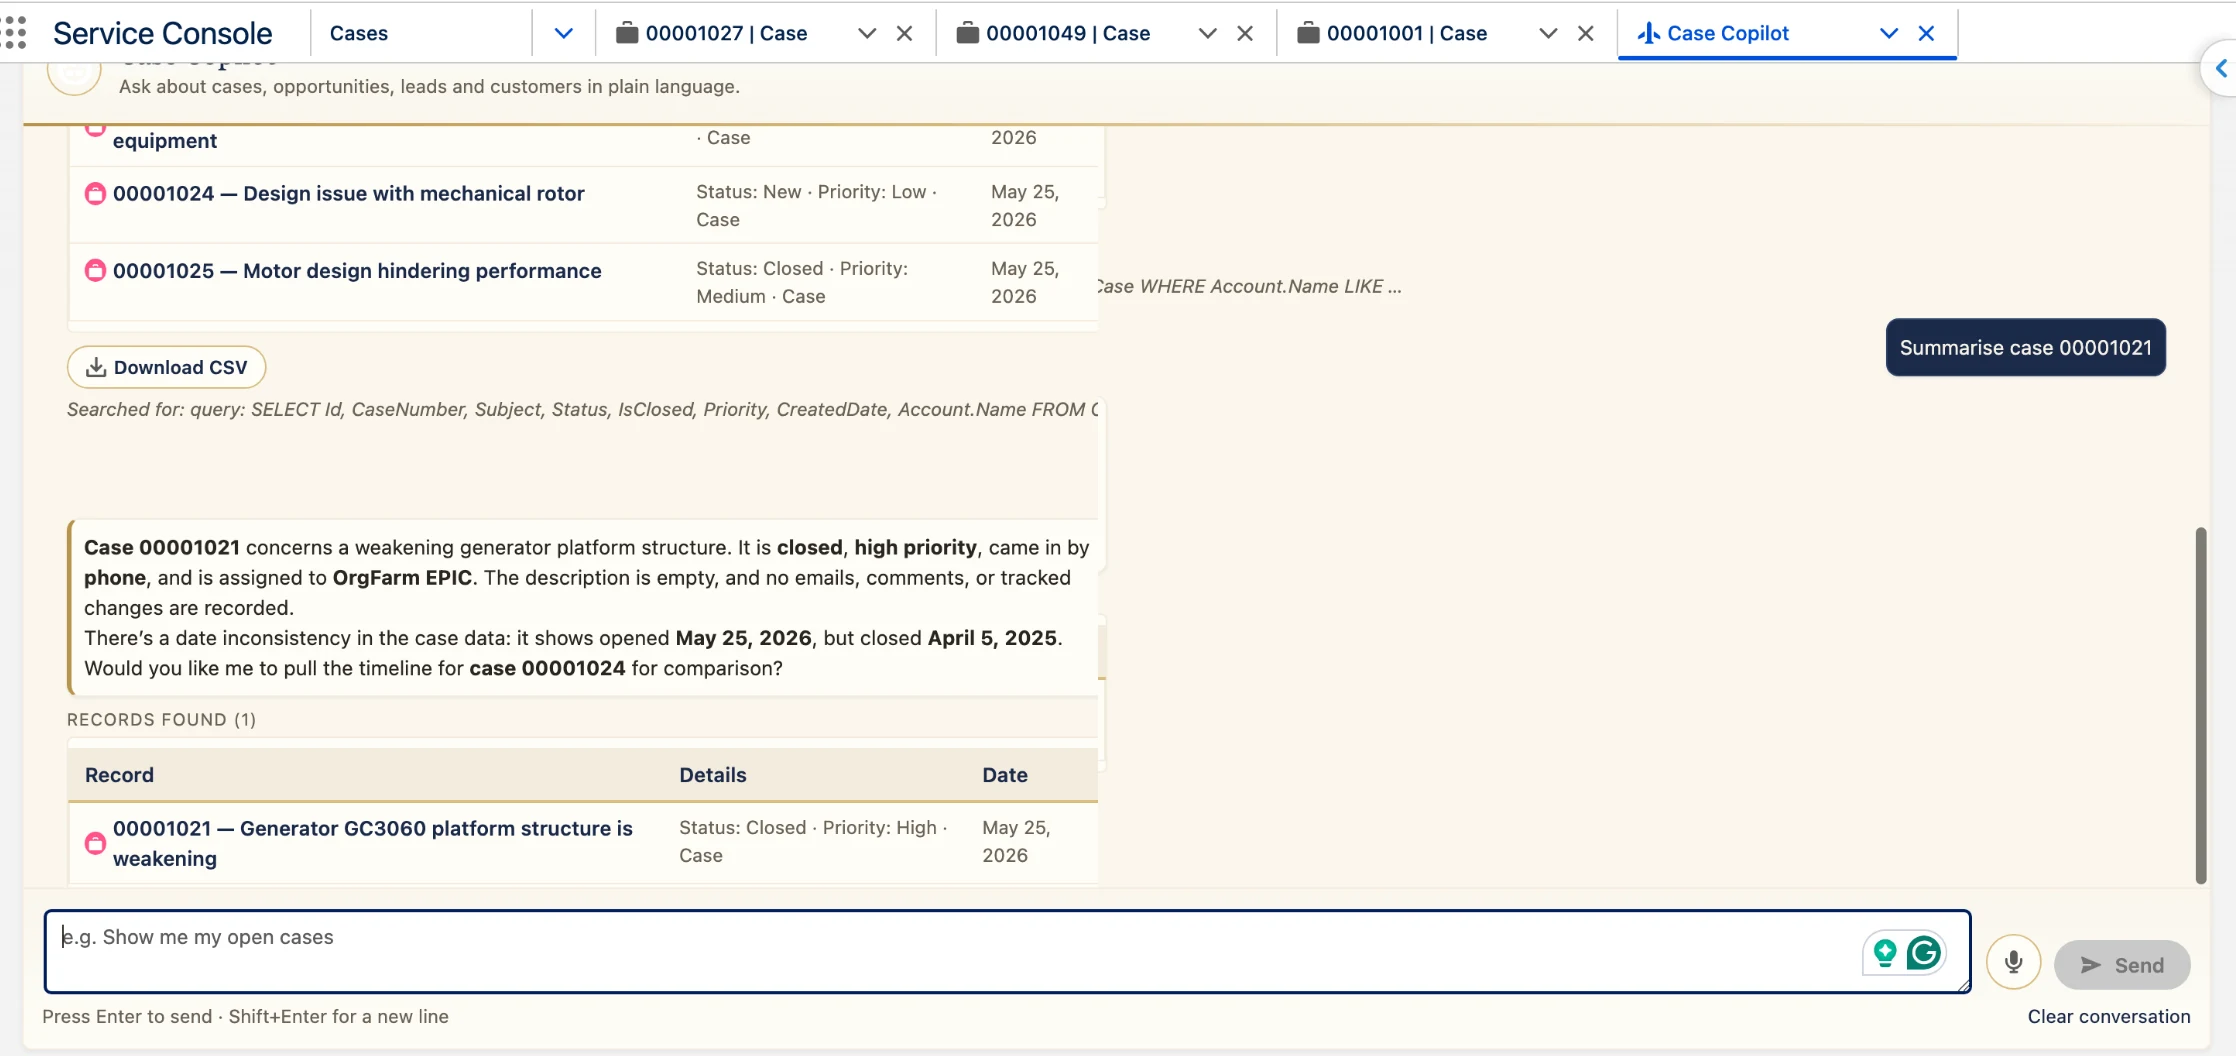
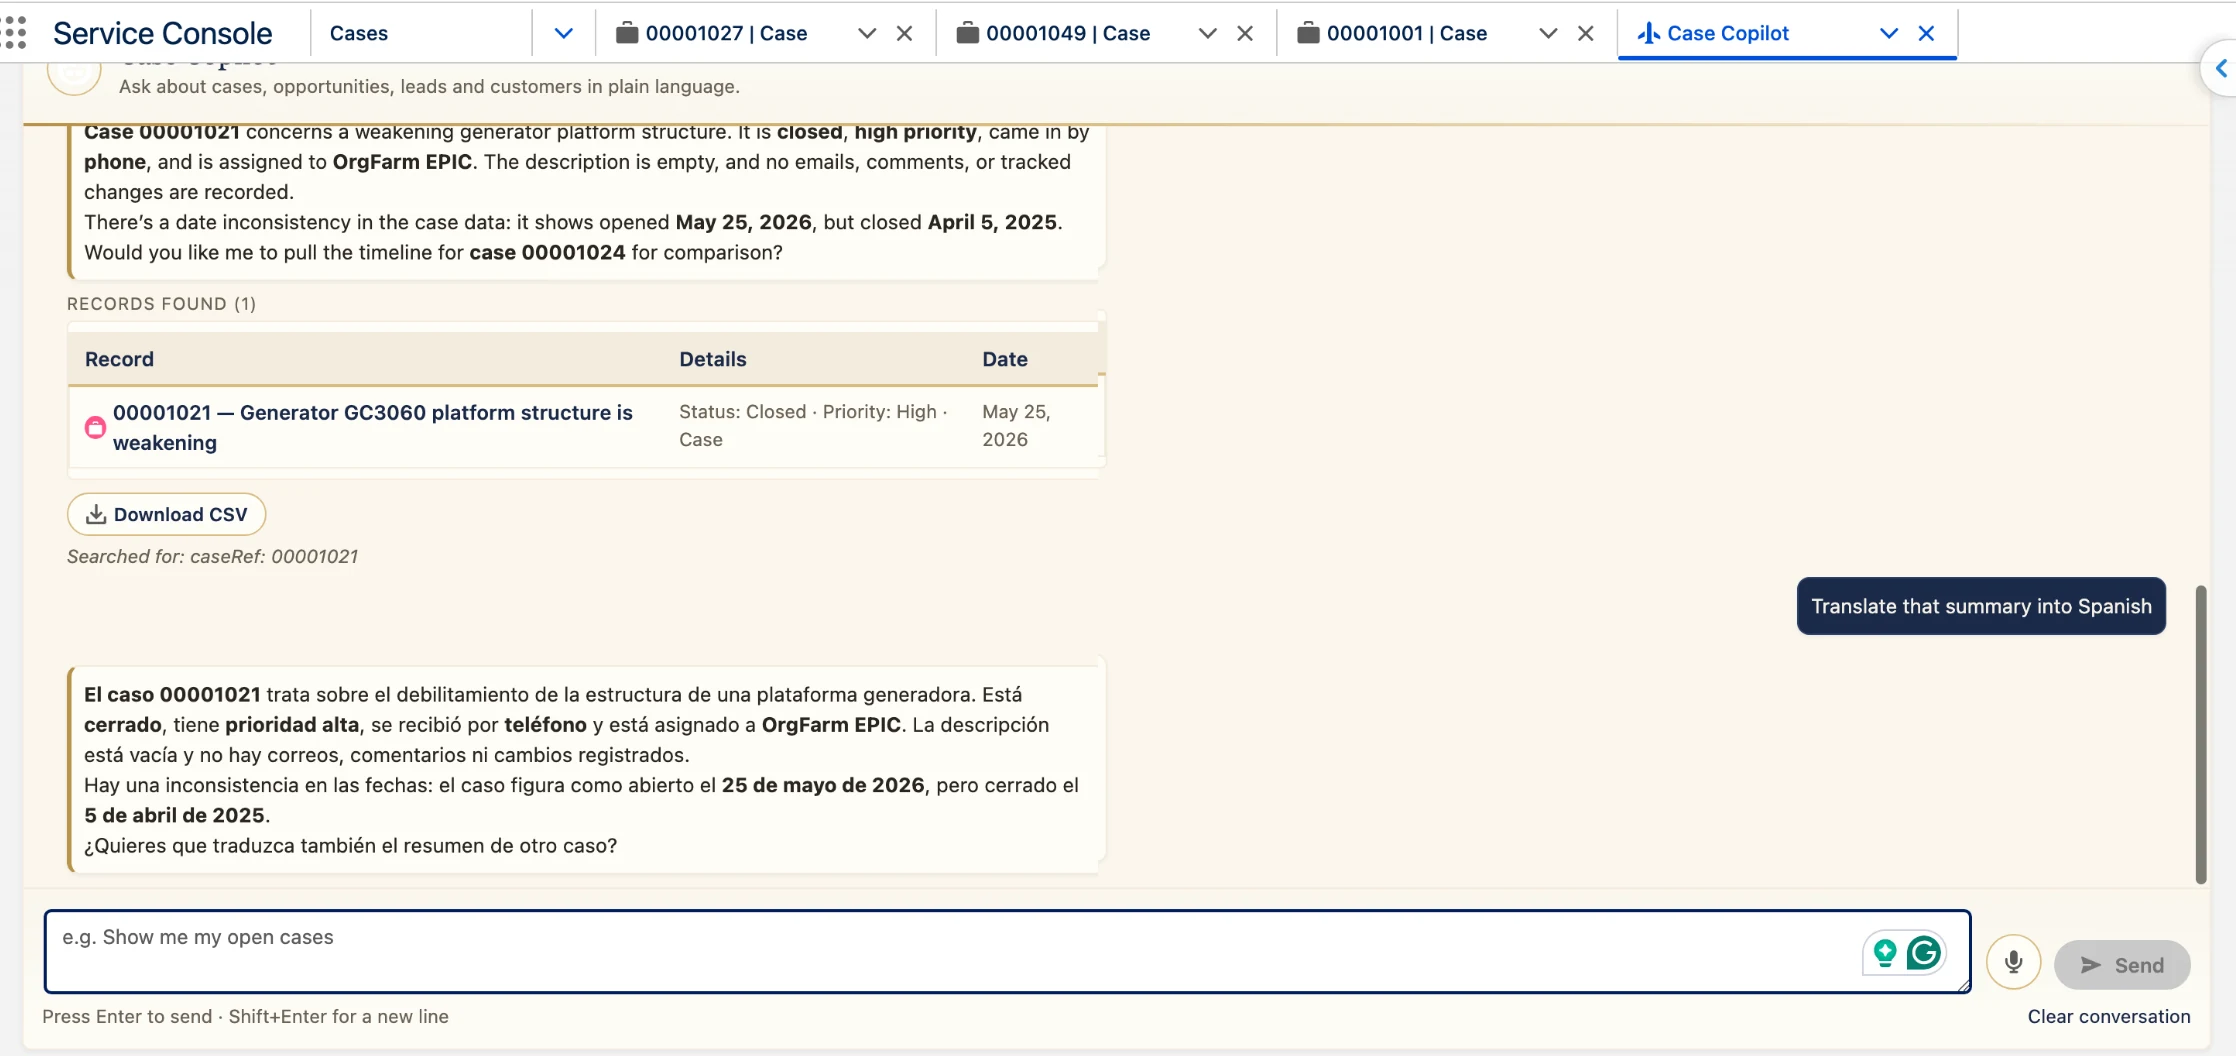
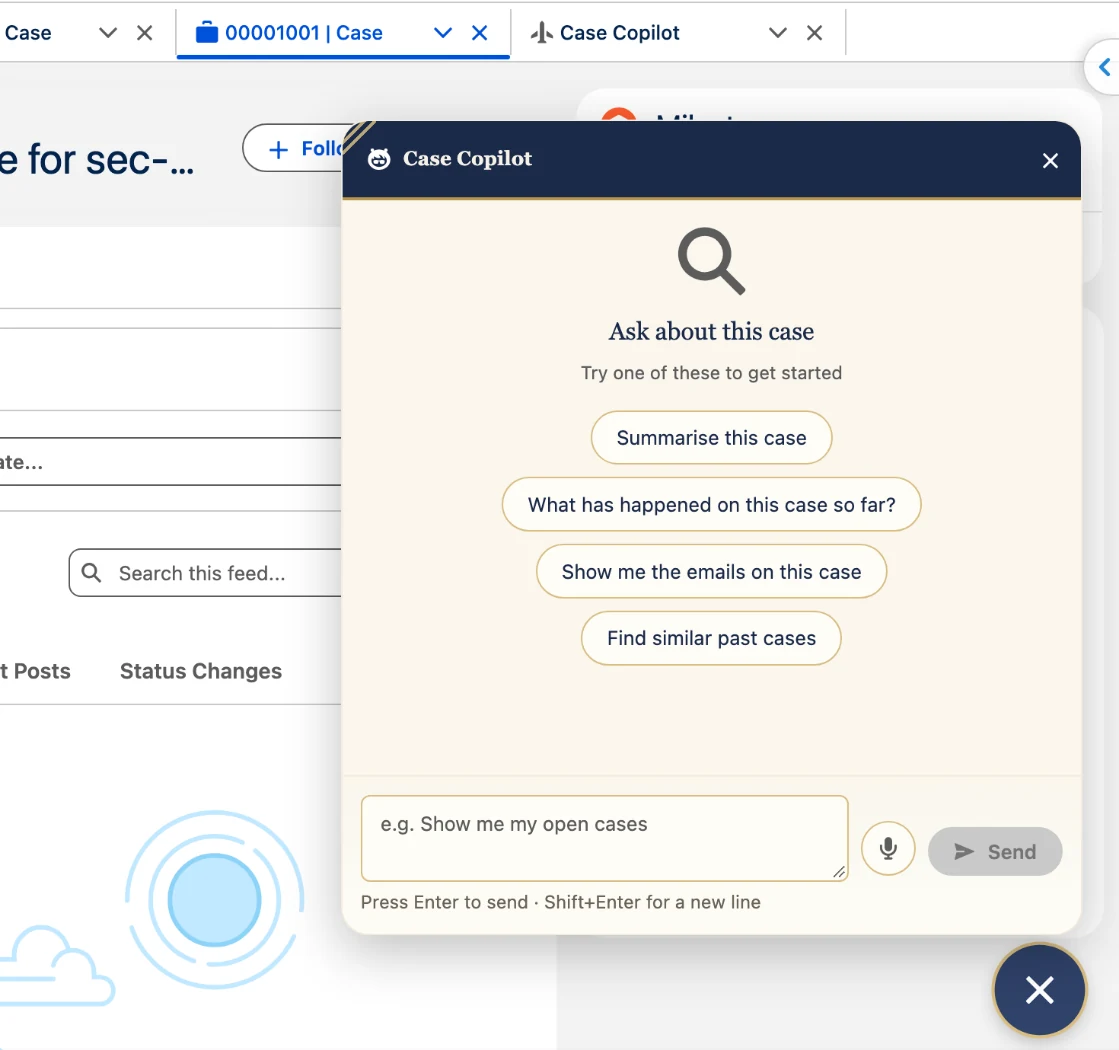
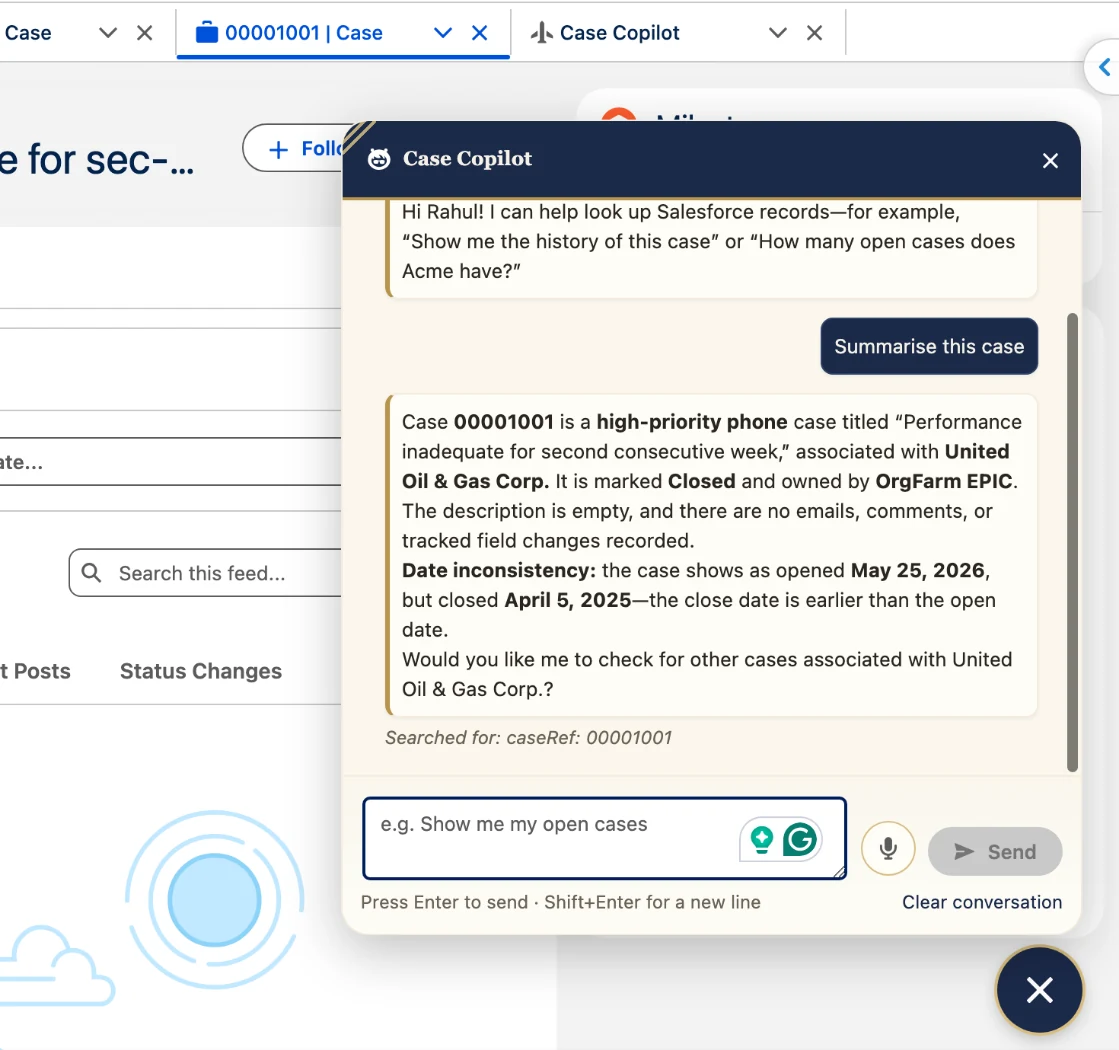
At a glance
What it does, in six lines
Cost
The same question, priced two ways
Agentforce bills each action an agent takes. Holocron bills only the tokens the model reads and writes, at the provider's own rate. The bars below are drawn to one scale.
| Questions per month | Agentforce, 2 actions | Holocron, no caching | Holocron, 25–55% cached |
|---|---|---|---|
| 1,000 | $200 | $2.16 | $1.21–$1.73 |
| 5,000 | $1,000 | $10.78 | $6.05–$8.63 |
| 10,000 | $2,000 | $21.55 | $12.10–$17.26 |
| 25,000 | $5,000 | $53.88 | $30.26–$43.15 |
How the numbers were made: Agentforce is 20 Flex Credits per action at $500 per 100,000 credits (list prices as of 2026). Holocron uses token counts logged from 107 tested questions (two-tool-call questions averaged 19,088 input and 493 output tokens) priced on GPT-6 Luna at $0.10 per million input tokens, $0.01 cached and $0.50 output. This is usage cost only. Licences are left out on both sides, and so is the effort to build and maintain a custom assistant. Full calculation.
Model choice
Changing the model is a dropdown, not a deployment
Holocron supports OpenAI and Anthropic models today, with more providers on the way. An administrator picks a model by name and the next question runs on it.
OpenAI
- GPT-6 Luna
- GPT-6 Astra
- GPT-6 Sol
- GPT-6.1 Sol
- GPT-5.6 Luna
- GPT-5.6 Sol
- GPT-5.6 Terra
- GPT-5.5
- GPT-5.4
- GPT-OSS 120B
- GPT-OSS 20B
Anthropic
- Claude Opus 5.5
- Claude Fable 5
- Claude Sonnet 5
- Claude Opus 5
- Claude Opus 4.8
- Claude Opus 4.7
- Claude Haiku 4.5
Coming next
- Google Gemini
- Qwen
- Z.ai GLM
Models are served through AWS Bedrock today. Direct Azure AI Foundry and Google connections come next.
In progress
Who is spending what, to the minute
Every answer already writes its token counts to a usage log inside Salesforce. Next, that log becomes a dashboard: tokens, cost and questions for any period, broken down by user, current as of the last refresh.
By user
| User | Questions | Tokens | Cost |
|---|
The people and figures in this preview are invented, sized from the real averages in the cost section and priced at GPT-6 Luna rates. The log it will read is real: in the development org so far it holds 40 answers, 303,788 input tokens (64% read from cache) and 7,889 output tokens, which comes to about 1.7 cents.